

Blog
Notes on how AI agents fail, what actually improves quality, latency, and cost, and the teams shipping on evidence instead of vibes.
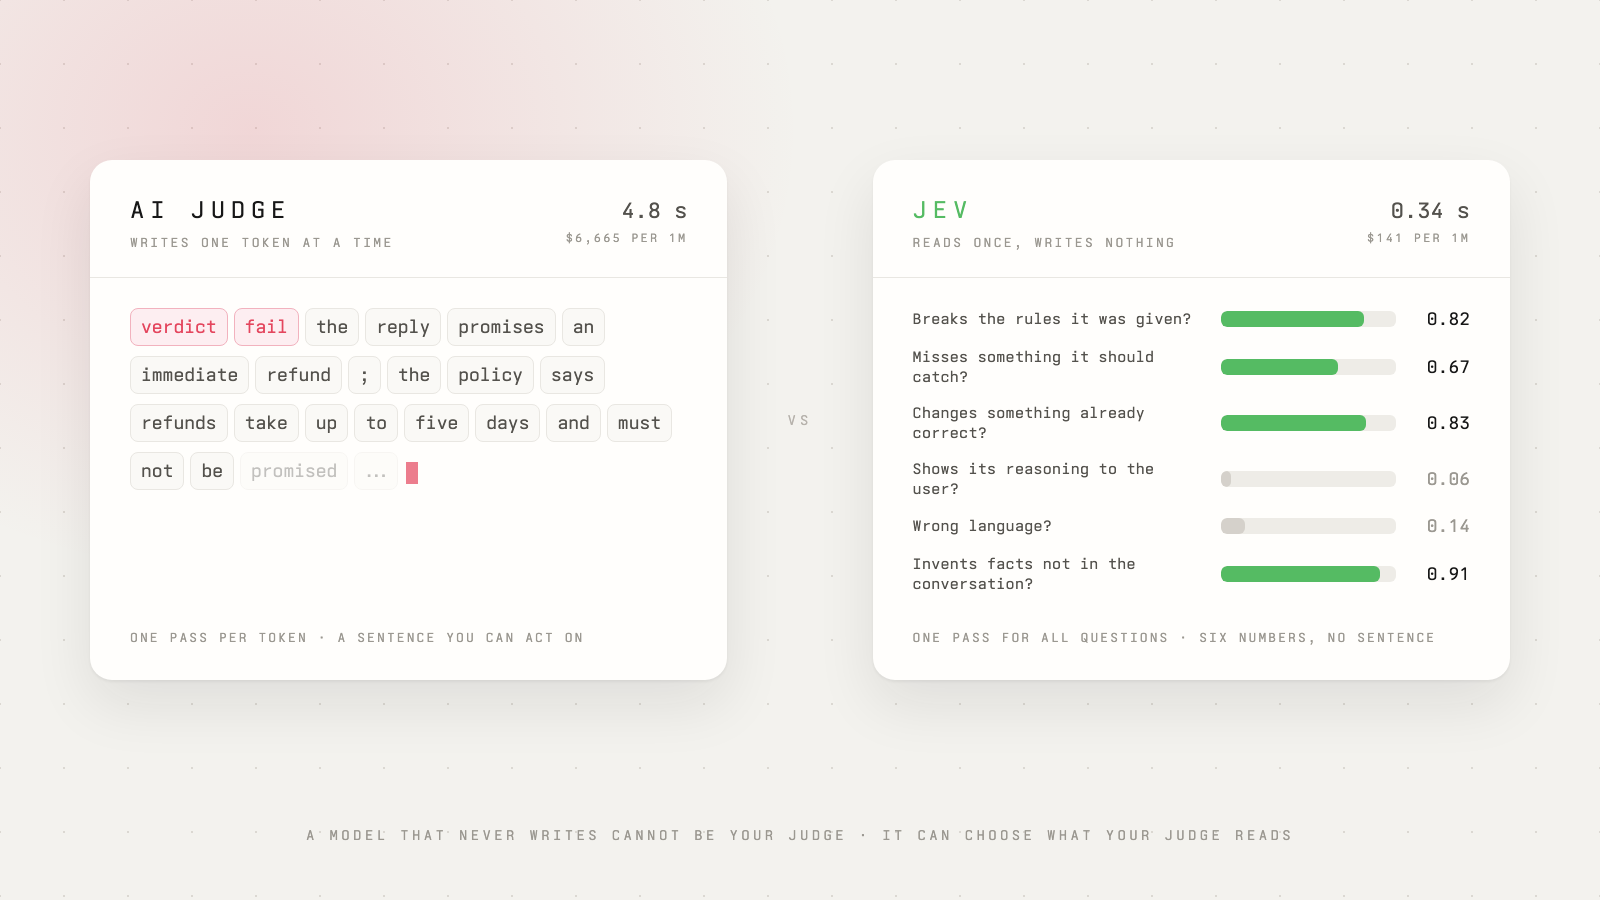
Jev vs the AI Judge: can a decision model replace it in production?
TypeSafe's Jev answers questions about a text without writing a word. We put it in front of our AI Judge on two evaluation scenarios and roughly 15,000 requests, asking two things: can it replace the AI Judge, and can it say what went wrong.
 Raúl Moreno Salinas ·
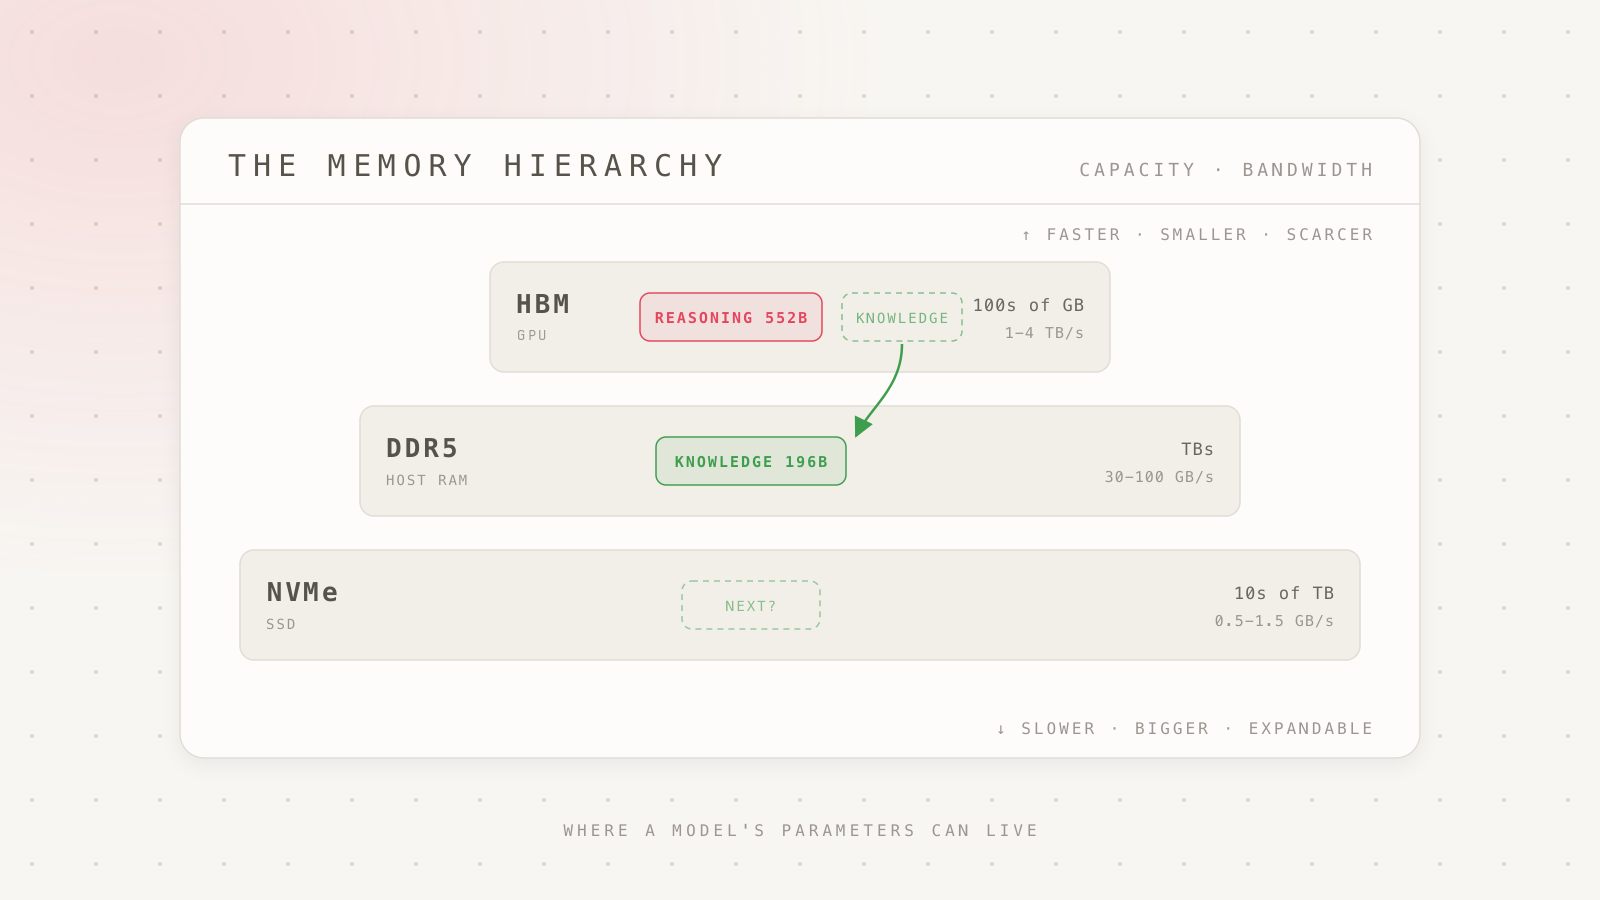
Knowledge just moved out of the GPU
DeepSeek and Qwen just agreed on where a model's facts should live: in host RAM or on an SSD, not in GPU memory. Here's how that split changes what it costs to run a model, and what it means if you want to own a specialized one.
 Ximo Guanter ·
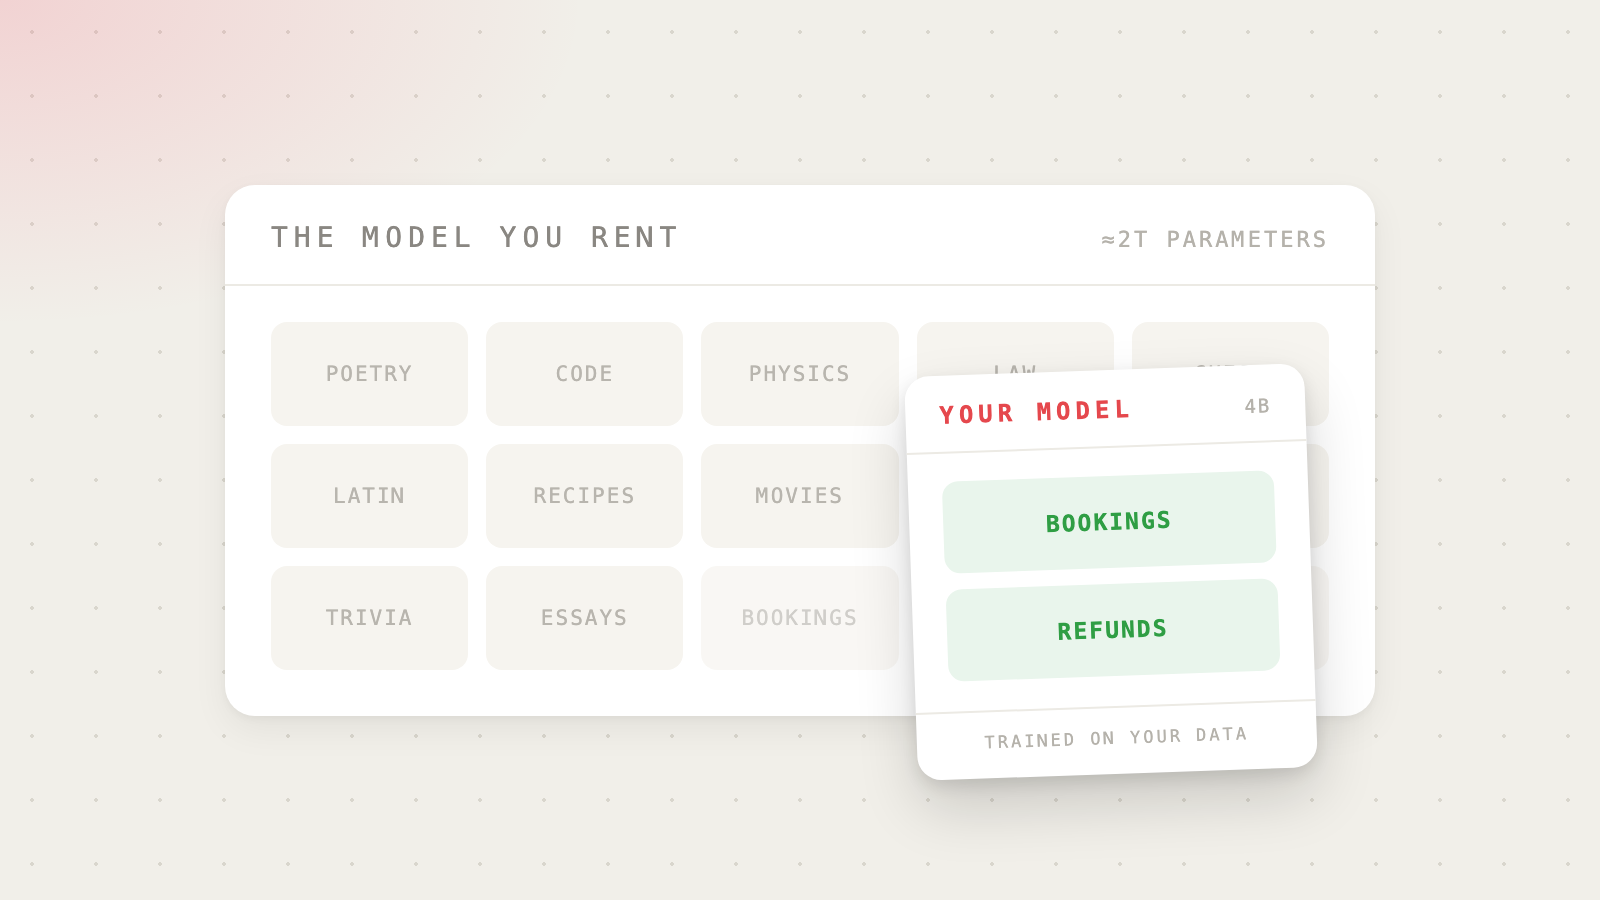
Your business can fit in a smaller model
An introduction to the world of open-weight models for businesses wondering whether they could own their AI, where a specialized model trained on your own data can match the big ones at a fraction of the cost and latency, and where the data you already have matters more than any model you could pick.
 Dani Rodríguez Hernández ·
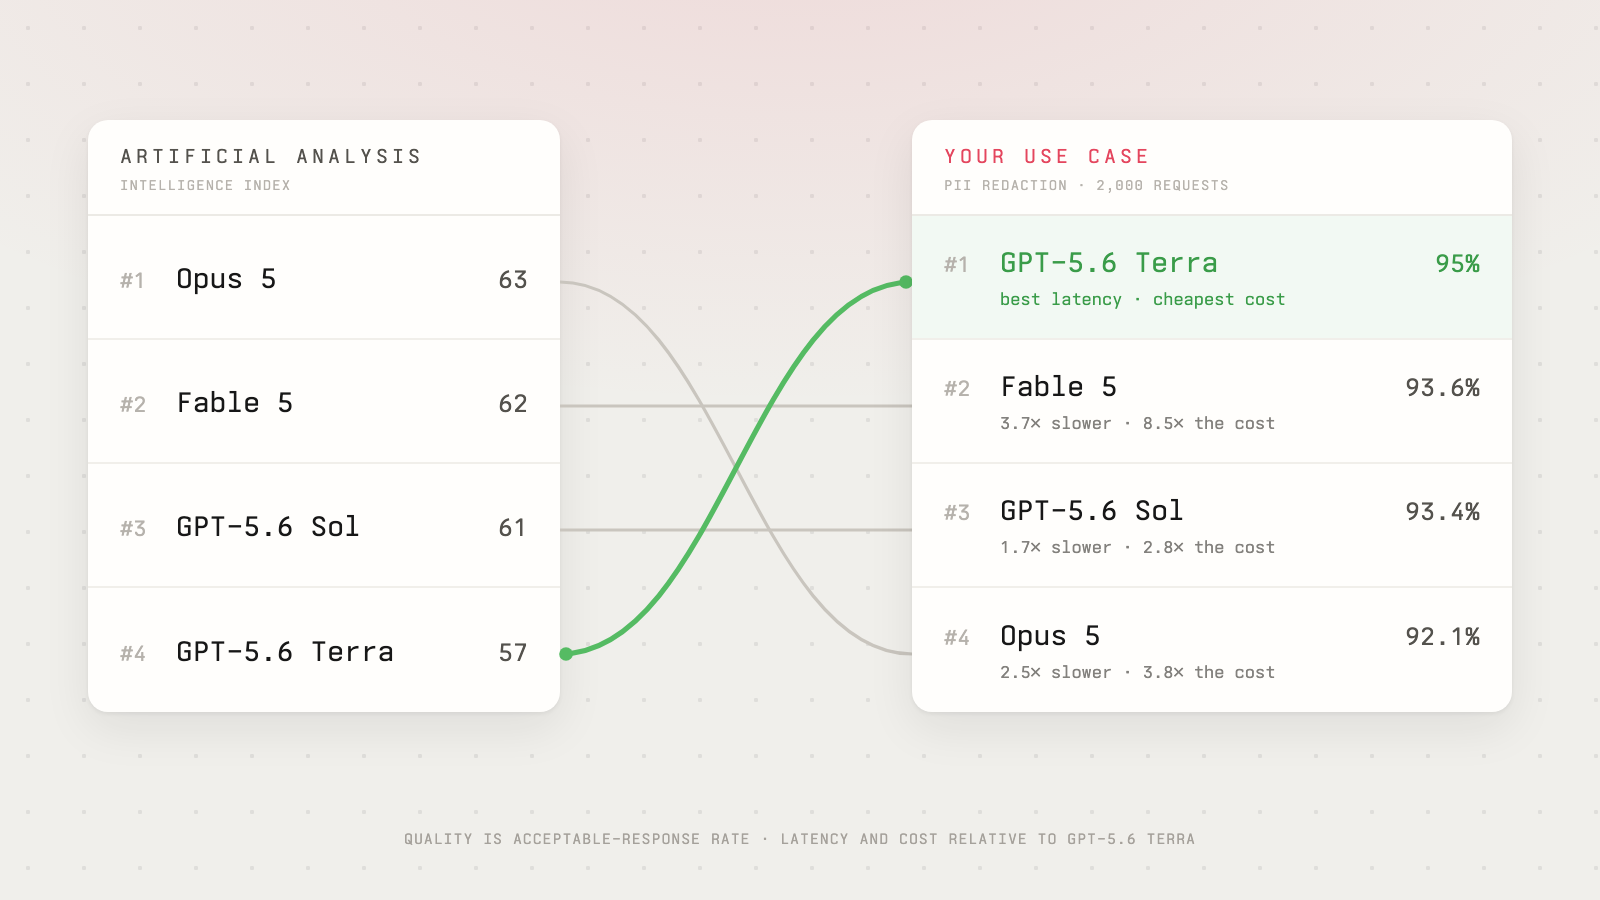
Your use case is not on the leaderboard
We replayed 2,000 real PII-redaction requests through seven frontier models. The winner is one no leaderboard would have picked.
 Andrea Moscatelli ·
Hello, world. We're round3.
We started a company to answer the hardest question in production AI: is this change actually better?
 Borja Burgos ·